Tprrt's Blog

Embedded Linux, Zephyr RTOS, open-source hardware, Linux gaming, retro gaming, and competitive fitness

Sep 25, 2026

One Entity, Many Bullets: Fitting a Projectile Pool Into the ECS

Introduction

The previous article described the static, no-heap Entity Component System framer-engine runs on GBA and NDS: fixed tables of component slots and entities, sized for a machine with no malloc(). With today's component set the table has room for 64 real entities. A caravan-style vertical shoot-'em-up, the engine's first playable milestone, wants several hundred bullets on screen in a dense pattern. The entity table cannot grow to fit that, and the pattern cannot cap itself at 64 shots.

Note

framer-engine is a personal side project. The source code will be made publicly available once the engine reaches a sufficient level of maturity.

The usual answer is not to make every bullet an entity. The simulation, a flat array of structs advanced by one system, was easy. Drawing that array without opening a second path in the renderer took two attempts. The first shipped, worked, and was wrong in a way no test would catch. The second was smaller, matched a pattern the engine already had, and surfaced three bugs across three rendering backends, none about bullets.

The first answer: a queue that isn't an entity

Hundreds of short-lived things, updated and drawn every frame and never addressed individually, suggest a per-frame queue: a flat array of draw commands (position, sprite, frame), reset each frame, appended to by whatever wants something drawn and consumed once by the renderer. A bullet pool fits exactly, pushing one entry per live bullet after the physics step, and needs nothing from the ECS: no entity, component or query.

That was the problem. Everything else the engine draws (a sprite, a tilemap, a HUD label) is an entity with a component, and every renderer's draw phase is systems iterating queries. A queue fed by application code and drained by the renderer is a second path. The entity-inspection API cannot see it, capability queries do not know it exists, and the debugging tools built on "the ECS is the whole scene" miss it. Bullets appeared in the right place at the right speed, but elements without an entity bypass the engine's core model. It is a different design that happens to render the same pixels.

The second answer: an entity that stands for many

framer-engine already had a component for this class of problem: a Tilemap is one entity whose component points at a grid the owner keeps, and the renderer draws the whole grid from that entity. Nothing in "many drawn things, one external memory, one component pointing at it" is specific to tiles. The rewrite generalizes it as SpriteBatch, and the bullet pool becomes one more caller instead of a bespoke path:

struct framer_batch_sprite {
    int32_t x, y;       /* center, world units, fixed point */
    uint32_t texture;
    uint8_t frame;
    uint16_t size;       /* drawn size, world units, fixed point */
};

struct sprite_batch {
    const void *first;   /* owner's element array */
    const uint16_t *count; /* owner's live-element count */
    uint16_t stride;      /* bytes between elements */
};

A framer_bullet has its own struct framer_batch_sprite as its first field, so the pool's storage array is the SpriteBatch element array, with no copy and no second buffer to keep in sync. framer_bullet_pool_entity_create() gives the pool's one entity a BulletPool component, stepped each frame by a physics system, and a SpriteBatch component built from the same array, drawn each frame by the renderer. Every draw phase still iterates a query and draws what it finds. The bullets stay out of the 64-slot entity table, and everything drawn is reachable from an entity.

Every renderer backend has to learn to draw the new component independently, which gave each one a chance to get it wrong.

Bug 1 (Vulkan): a guard that was checking the wrong component

Each backend's sprite system is imported once per world, so it needs a guard against importing twice. Comparing the stored world pointer with the current one breaks when a different world is allocated at the same address, which every test here does by tearing a world down and creating a fresh one. The convention in the renderer imports is to also check that a component the import function itself registers is present on the world.

The check written for SpriteBatch tested the wrong component:

/* Wrong: Sprite is registered by the renderer's own import, before
 * this function ever runs -- it says nothing about whether THIS
 * function has run on this particular world. */
if (s_world == world && FRAMER_COMPONENT_IS_REGISTERED(world, Sprite))
    return;

On a fresh world reusing a previous world's address, Sprite is already registered by the caller, earlier in the same framer_sprite_system_import(), before the guard runs. The check reports "already set up" on the first call and the function returns without registering SpriteBatch or its draw system. Sprites drew; batches never did.

A test caught it. The new pixel-readback test for SpriteBatch (draw an element, read the pixel back, expect it filled) passed on the software and OpenGL backends and failed on Vulkan, whose suite happened to run a batch test on a world at an address a prior test had used. The fix checks the component this function registers:

if (s_world == world && FRAMER_COMPONENT_IS_REGISTERED(world, SpriteBatch))
    return;

The OpenGL and software backends had the identical guard, found by inspection before either failed a test. Both got the same fix and were verified.

Bug 2 (OpenGL): reading back a write that hasn't happened yet

The OpenGL backend compiles its default shaders lazily, on first request, and caches them in the world's Shader singleton component:

const struct shader *shaders = FRAMER_GET(world, FRAMER_ID(Shader), Shader);
if (!shaders) {
    unsigned int sprite = framer_shader_create(...);
    /* ... compile the other three default shaders ... */

    FRAMER_SET(world, FRAMER_ID(Shader), Shader, .sprite_shader = sprite, /* ... */);
    shaders = FRAMER_GET(world, FRAMER_ID(Shader), Shader);
    if (!shaders)
        return 0;
}

switch (type) {
case SHADER_TYPE_SPRITE: return shaders->sprite_shader;
/* ... */
}

This assumes a component write takes effect immediately. It does not: a write issued inside a running system is staged and merged once every system in that step has finished. A second system in the same step can see it, but the call that made the write cannot read it back. That is an ordinary property of this ECS. Every other caller of framer_shader_get_default() came after something upstream (loading a level, spawning a player) had already asked for a shader on an earlier frame, so the singleton existed.

The SpriteBatch draw system is the first thing in a new scene with nothing upstream: no mesh, no plain sprite, just a bullet pool's entity. On the first frame its render system is the first caller of framer_shader_get_default(). The write lands, the read-back in the same call finds nothing, the function returns 0, and that frame renders every batch element with no shader bound. The ECS timing is fine; the fix stops reading back what was just staged:

struct shader created = {.sprite_shader = sprite, /* ... */};

framer_component_set(world, FRAMER_ID(Shader), FRAMER_ID(Shader), &created);
return shader_of_type(&created, type);

Bug 3 (all three desktop backends): drawn correctly, in the wrong order

The first two bugs were "nothing drew". In the third, every bullet drew at the right position, size and texture, but the entity that fired them disappeared behind its own bullets once enough piled up at its position.

SpriteBatch and the per-entity Sprite draw are separate systems in the same ECS phase, and nothing said which goes first. On GBA and NDS the hardware settles it: OAM sprites carry a priority, and entity sprites are drawn at a higher priority than batch elements, so an entity is in front of a batch whatever the system order. Sampling the OAM through mGBA's debug stub mid-run confirms it: the emitter (the round blue sprite at the center) sits in front of the spiral it fired:
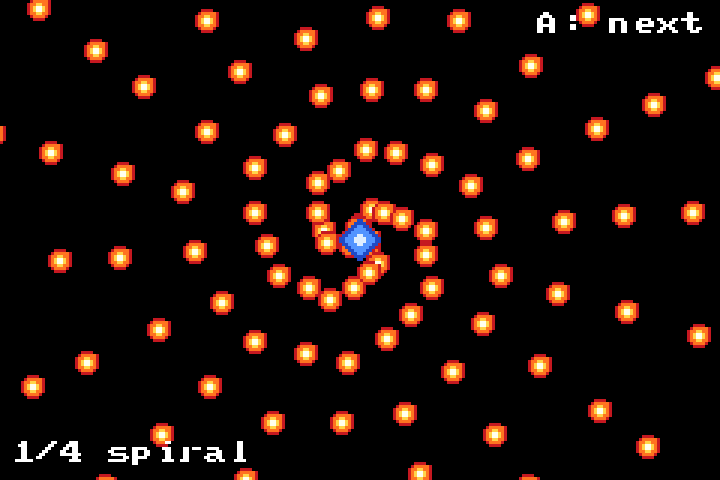
The bullets example running under mGBA, OAM contents captured over its debug stub -- a blue emitter sprite is clearly visible on top of a spiral of orange bullet sprites radiating from it

The bullets example's spiral pattern, OAM contents read directly off a running GBA — the emitter draws in front of every bullet it fires, by hardware priority, regardless of draw order.

The three desktop backends (OpenGL, Vulkan, software) have no such guarantee: draw order is their only ordering mechanism, and the two systems registered in whatever order the import code called them, which put SpriteBatch after the entity sprite system. Sampling framebuffer pixels at the emitter's position every fifty frames of a Vulkan run shows the failure: the emitter's blue for hundreds of frames, then, once enough live bullets reach that pixel, whatever bullet is passing through it:

frame  350: 2850c8 5a96ff 5a96ff 5a96ff 2850c8   (emitter blue)
frame  750: 2850c8 5a96ff 5a96ff 5a96ff 2850c8   (emitter blue)
frame  800: c81e28 ff7828 ffdc50 ff7828 c81e28   (bullet red/orange)
frame 1200: c81e28 ffdc50 fffff0 ff7828 c81e28   (bullet, still)

The fix declares the order explicitly instead of relying on registration order, on every desktop backend:

static const struct framer_system_dep batch_deps[] = {
    {.before = "sprite_render_system", .after = NULL}};

framer_system_register(world, "sprite_batch_render_system",
                        FRAMER_PHASE_ON_UPDATE,
                        sprite_batch_render_system, bq, batch_deps, 1);

A new renderer test pins it down: a red entity sprite and a white batch element on the same pixels, asserting the pixel reads back red.

Verification: one bug per backend, so one check per backend

The design is not backend-specific, but each backend had its own bug, so each was checked separately. The desktop pixel-readback tests (software, OpenGL, Vulkan) ran the same three scenes. examples/bullets was cross-compiled for GBA and NDS and its OAM sampled through mGBA's debug stub, the technique the dithering article used to catch a hardware-only bug. Every GBA example ROM was booted headlessly to check that a related fix did not regress startup: one more component pushed the fixed-stride storage layout past EWRAM, so component storage is now pooled.

One result was the same everywhere I checked: with the spiral pattern running continuously, the live bullet count settles in the high 90s on GBA, OpenGL and Vulkan alike.

Where this goes next

FRAMER_STATIC_MAX_COMPONENTS (40) and FRAMER_STATIC_MAX_ENTITIES (104, leaving 64 for game use) both grew slightly to fit the new component without pushing the pooled storage past EWRAM on GBA. What remains for the bullet pool is measuring and documenting the per-target bullet ceiling. The capacity constants (examples/bullets uses 128 on GBA/NDS, 1024 on desktop) were picked before there were numbers to size them against.
posted at 21:40  · 8 min read  ·   ·  ecs  rendering  vulkan  opengl  gba  nds  embedded  retro  gamedev  c  article

Aug 13, 2026

Sixteen Offsets, Two Patterns: Debugging GBA's Ordered-Dither Translucency

Introduction

The two previous GBA articles, on cycle-level optimization and the no-heap ECS underneath it, were about working around hardware with no float unit and no polygon fill. This one is about an older constraint on the same hardware: the GBA's Mode 4 framebuffer is 8bpp indexed, and its palette is a single unbuffered 256-entry table with no double-buffering and no VBlank gating on writes. Reassigning a palette slot recolors every pixel already on screen that uses it, immediately, mid-frame if the timing is unlucky.

That rules out blending per pixel and allocating the result a palette slot on the fly. Blending would also be too slow. framer-engine's GBA backend rasterizes 3D faces in software on a 16.78 MHz ARM7TDMI with no hardware alpha unit, and the earlier optimization article spent its length shaving cycles off this rasterizer's inner loop. Blending means mixing source and destination colors and resolving the result to a palette index for every covered pixel of every translucent face, every frame. Dithering avoids that: the per-pixel decision is one threshold compare against a precomputed matrix, with no blend math and no palette search. Translucent faces are drawn to roughly the fraction of screen cells their alpha implies, using a fixed Bayer matrix, so the density of drawn pixels approximates the alpha.

Note

framer-engine is a personal side project. The source code will be made publicly available once the engine reaches a sufficient level of maturity.

That part worked the first time. What failed, twice and in two different ways, both visible only on real hardware, was making overlapping translucent objects dither differently enough from each other to stay visible. The second bug is a quieter version of the first, and the fix that stuck came from building three ROMs and looking at them, not from a smarter formula.

The setup: one matrix, one offset per object

The dithering is a small pure function. Given a matrix of thresholds and a per-object level (roughly alpha out of 16), a pixel draws if the matrix value at its screen coordinate is below the level:

static const unsigned char DITHER_BAYER_4X4[4][4] = {
    {0,  8,  2, 10},
    {12, 4, 14,  6},
    {3, 11,  1,  9},
    {15, 7, 13,  5},
};

static inline bool dither_should_draw(int x, int y, int level)
{
    return DITHER_BAYER_4X4[y & 3][x & 3] < level;
}

That is enough for one translucent object, not for two. examples/translucent_cubes draws three overlapping cubes (red, green, blue) at the same alpha, back to front. With no per-object variation they test the same screen cells against the same level, so they draw to the same pixels, and the nearest cube overwrites the farther ones where they overlap instead of blending with them. Each object needs its own dithering phase: a draw-set that differs from its neighbors' while still covering the right fraction of pixels.

Bug 1: shifting the coordinate collapses sixteen phases into two

The obvious way to give each object a phase is to shift the sampled coordinate before indexing the matrix: object i looks up BAYER[(y + py) & 3][(x + px) & 3] for some per-object (px, py). That gives sixteen (px, py) pairs and, apparently, sixteen phases. It passed review and looked right in the emulator.

It did not look right in the screenshots from hardware. With three overlapping equal-alpha cubes, the middle one, green, was almost invisible wherever it overlapped blue.

examples/translucent_cubes running in mGBA with the coordinate-shift bug — only red and a dark, almost-black region are visible, no green or blue

examples/translucent_cubes at the commit that shipped the coordinate-shift phase. Green and blue have collapsed into the same draw-set as another object and vanished.

Enumerating all sixteen shifts against the 4x4 matrix at that alpha level showed the cause: only two distinct draw-sets exist among the sixteen shifts. The 4x4 Bayer matrix has translational symmetry, so every shift is equivalent, cell for cell, to another shift with the same parity of (px + py). Two objects in the same parity class draw to identical cells, and the nearer one erases the other. Three objects and two parity classes guarantee a collision.

The fix: rotate the compared value, not the sampled coordinate

The working version leaves the coordinate alone and rotates the value read from the matrix by a per-object offset before comparing it with the level:

static inline bool dither_should_draw(int x, int y, int level,
                                       int offset)
{
    return (int)((DITHER_BAYER_4X4[y & 3][x & 3] + offset) & 15) <
           level;
}

DITHER_BAYER_4X4 is a bijection: its sixteen cells hold the values 0 to 15 once each. The cells with (value + offset) mod 16 < level form a level-sized contiguous arc of that range, and as offset goes from 0 to 15 the arc's start visits every residue once. Sixteen offsets give sixteen distinct draw-sets at every level, by construction and not just for the alpha I tested, as sixteen Caesar shifts give sixteen distinct ciphertexts. This shipped and the green cube reappeared. The next report from hardware was different: not invisible, but rougher than the other two.

examples/translucent_cubes running in mGBA after the value-rotation fix — all three cubes visible, but the third one's dither pattern looks visibly rougher than the other two

The demo after the value-rotation fix. All three cubes are visible, but the thinnest sliver, drawn last and forced onto a worse offset, already reads rougher than its neighbors.

Bug 2: only two offsets out of sixteen are smooth

"Rougher" was exact. At the alpha level examples/translucent_cubes uses, offset 0 produces a perfect alternating checkerboard:

offset=0                     offset=1
#.#.#.#.                     #.#.#.#.
.#.#.#.#                     .#.#.#.#
#.#.#.#.                     #.#.#.#.
.#.#.#.#                     .#.#.#.#

Only one other offset (8, half the matrix's sixteen values away) produces the other perfect checkerboard, disjoint from offset 0's. Every offset in between is the same pattern with a few cells flipped, less regular the farther it sits from 0 or 8. Three overlapping objects need three distinct offsets, which the previous fix gave, but with only two perfect offsets in a 16-value matrix the third object is forced onto an irregular one. That is a structural property of a small matrix, not a bug in the value rotation.

A bigger matrix buys a finer gradient, not an exemption

An 8x8 matrix (64 distinct values) does not remove the "only two perfect offsets" property; the argument above does not depend on matrix size. It gives a much finer gradient around the two perfect points, so a third offset near either one looks close to perfect. The caller contract is unchanged: levels still run from 0 to 16, and the comparison is rescaled by 4 to match the 8x8 matrix's 0-63 range:

static inline bool dither_should_draw(int x, int y, int level,
                                       int offset)
{
    return (int)((DITHER_BAYER_8X8[y & 7][x & 7] + offset) & 63) <
           level * 4;
}

The third cube went from "noticeably wrong" to "close to right". That still did not fix the problem that mattered.

The bug the roughness metric couldn't see

The offsets came from a 64-entry table ranked by how close each offset's own pattern is to a perfect checkerboard: offset 0 first, offset 32 (the 8x8 matrix's other perfect point) second, then the next closest. For three visible objects the table handed out 0, 32, 1.

Offset 1 is individually an excellent choice: one flipped cell out of sixty-four. The ranking never asked how much offset 1's draw-set overlaps offset 0's. The answer is 31 of 32 drawn cells identical. The third object was again drawing to almost the same pixels as the first, which is the original bug in a better disguise: "individually smooth" and "well separated from neighbors" are different properties, and the ranking had conflated them.

Testing three sequences instead of guessing

Fixing the separation analytically hit a trade-off. Offsets chosen only to maximize separation, spread evenly over the 64-value range, land on values like 16 and 48, which render as regular vertical or horizontal stripes instead of checkerboard noise:

offset=1 (roughness-ranked)      offset=16 (separation-first)
#.#.#.#.                         #.#.#.#.
.#.#.#.#                         #.#.#.#.
#.#.#.#.                         #.#.#.#.
.#.#.#.#                         #.#.#.#.
#.#.#.#.                         #.#.#.#.
.#.#.#.#                         #.#.#.#.
#.#.#.#.                         #.#.#.#.
#..#.#.#                         #.#.#.#.

The stripe pattern shares 16 of 32 cells with its neighbors instead of 31, a large improvement by the numbers. But axis-aligned stripes are a textbook case of a dither that is more noticeable than diagonal checkerboard noise. More computation could not say whether that trade looks better than the near-miss checkerboard.

So I built three complete 64-entry offset sequences: the original roughness-ranked table; a separation-maximizing one, a bit-reversal permutation (a Van der Corput sequence, where entry i is the 6-bit binary reversal of i and every prefix is evenly spread over the offset range); and a capped-overlap middle ground. I compiled each into a translucent_cubes.gba ROM and ran them in mGBA. The separation-maximizing sequence won, stripes included.

static const unsigned char GBA_DITHER_OFFSET_SEQUENCE[64] = {
    0,  32, 16, 48, 8,  40, 24, 56, 4,  36, 20, 52, 12, 44, 28, 60,
    2,  34, 18, 50, 10, 42, 26, 58, 6,  38, 22, 54, 14, 46, 30, 62,
    1,  33, 17, 49, 9,  41, 25, 57, 5,  37, 21, 53, 13, 45, 29, 61,
    3,  35, 19, 51, 11, 43, 27, 59, 7,  39, 23, 55, 15, 47, 31, 63,
};
examples/translucent_cubes running in mGBA with the bit-reversal offset sequence — all three cubes visible, dither density looking even across all three

The demo with the bit-reversal sequence: three distinct, evenly separated offsets, with no object drawing to nearly the same cells as another.

Verifying a change with nothing to count

The GBA performance article relied on cycle_probe.py, a deterministic cycle count diffed between builds. It does not apply here: this is an output correctness question, and the claims are combinatorial. I checked each of them by construction in Python before writing the C: the sixteen distinct draw-sets of the value rotation, the exact pixel count at every level and offset of the 8x8 matrix, and the even prefix spread of the bit-reversal sequence. Each check enumerated every offset, level and pair. Every change also got the full desktop test suite, a GBA cross-compile and a headless mGBA run of examples/translucent_cubes. For the final sequence choice I looked at the rendered result, the only step that caught what the math could not.

Where this goes next

The bit-reversal sequence is one fixed table shared across every scene. It optimizes pairwise separation along the sequence, not for the specific set of objects overlapping in a given frame. For a small, fixed handful of translucent objects that is enough. A scene with many more would exhaust the best-separated entries and reach ones no better than the original bug. Assigning offsets jointly across the objects in use each frame is the next step if that happens.

posted at 11:00  · 8 min read  ·   ·  gba  rendering  dithering  embedded  retro  gamedev  article