Introduction
The earlier article on cycle-level GBA optimization
covered the software 3D rasterizer, where two "obviously correct" changes
measured as regressions once link-time optimization's inlining was counted.
Here the same thing happens in the text renderer, with two more wrong turns
that have nothing to do with LTO.
Note
framer-engine is a personal side project. The source code will be
made publicly available once the engine reaches a sufficient level of
maturity.
Two framer-engine examples with a lot of on-screen text ran far below
the 60 Hz target, both idle, nothing moving, no input needed to reproduce:
input_tester (76 of a 96-slot text sprite budget active) at roughly
18 FPS, and wordle, a word cloud of rotated labels, at roughly 14.5.
phase_probe.py, the gdbstub cycle-bracketing script used in earlier
articles, put about 69% of a frame's cost inside one function,
gba_text_render_system. Which part of it?
Finding where the cost lives
The function processes a handful of text entities, each with one or more
lines, each line made of several hardware sprites (one GBA OAM entry per
glyph group). Three plausible places for the cost to hide: the glyph
layout math, the screen-space projection that turns a world position into
a pixel coordinate, or the OAM attribute writes themselves, once per
glyph and so the most frequent of the three.
arm-none-eabi-objdump -dS ruled out the OAM writes: they are inlined
integer stores with no library calls. The projection math was different:
cx/cy (an entity's anchor in screen space) and py_base/px
(where each line starts) were float, and the ARM7TDMI has no FPU, so every
subtract, add, multiply, floorf() and float-to-int conversion goes
through a software float routine.
Static inspection shows that a call exists, not how often it runs. Two
breakpoints measured that: one at the function's entry, one at the first line
of the innermost per-sprite loop body. The delta between consecutive hits of the second breakpoint is one
sprite's own cost when it stays on the same line as the sprite before it,
and the same delta plus a line's or entity's own setup when it doesn't.
In a steady frame of input_tester, a same-line sprite-to-sprite step
cost about 515 cycles. A step that also crossed into a new line or a new
entity cost 7400 to 17000, roughly fifteen times as much. Those transitions are
rarer than sprites but frequent enough to dominate a frame. The per-entity and
per-line projection math was the cost, not the per-sprite work.
Attempt 1: fixed-point that rounded the wrong way
The engine's software 3D pipeline already uses fix_t, a Q12 fixed-point
type, where one hardware multiply (fix_mul) replaces a chain of soft-float
calls. Reusing it for text looked like the obvious fix: convert the camera
position, ortho extent, scale and entity position to fix_t and project in
integer math.
It looked right in every example. Before trusting that, I wrote a host-side
sweep test comparing the fixed-point result with the float one across a grid
of realistic camera, ortho, scale and position values. 16 of 192 combinations
disagreed, every one by exactly one, in the same direction:
mismatch: cam=0.0 ortho=5.0 scale=28.8 pos=0.0 expected=144 actual=143
mismatch: cam=0.0 ortho=5.0 scale=28.8 pos=2.5 expected=72  actual=71
The existing fix_from_float() helper (shared with the 3D rasterizer,
which depends on its exact behavior) truncates toward zero. Four
conversions chained together — camera, ortho extent, scale, position —
each truncate a little short, and on values that land exactly on an
integer in float math, the accumulated shortfall floors to one below the
right answer. Text at 144.0 pixels would have shifted by a pixel on specific
camera positions, with no visible sign.
Attempt 2: the float path that measured slower
Instead of fixing the rounding, I kept everything in float and replaced
(int)floorf(x) with a hand-rolled version. objdump showed the
floorf() body at 74 instructions, handling NaN, infinity and subnormals
that bounded screen-space input never produces. A truncate-then-adjust
version is exact for any finite value and looks much cheaper:
static inline int gba_fast_floor(float x)
{
    int i = (int)x;
    return (float)i > x ? i - 1 : i;
}
It is exact, verified like the first attempt, and shorter. cycle_probe.py
disagreed: the steady-state average on input_tester went from 727556 to
748028 cycles/frame, a ~2.8% regression. The original (int)floorf(x) is
two soft-float calls (floorf, then the float-to-int conversion). The
replacement is three (truncate, convert back to float, compare), and each call
pays its own call/return/Thumb-interworking overhead. floorf()'s large
body is cheaper than one extra call.
What actually worked
Fixed-point, with the rounding fixed: a local gba_fix_from_float_rounded()
that rounds to nearest. The shared fix_from_float() stays untouched because
the 3D rasterizer depends on its truncation. The sweep test now passes,
including the exact-integer cases and the narrowest float margin around an
integer boundary.
The second change mattered as much: every frame-constant term (camera
position, ortho extent, screen-space scale) is converted to fix_t once per
call, not once per entity. Only the entity's own position is converted per
entity. fix_mul is one hardware multiply, and flooring a fix_t to a
pixel coordinate is an arithmetic right shift, with no library call.
A rotated text entity still needs a float cx/cy for the sprite-rotation
math. Computing it from scratch next to the fixed-point version made a rotated
entity pay for both, which was slower than before for that case;
cycle_probe.py on wordle's word cloud confirmed it. Deriving the float
value from the fix_t one (one int-to-float conversion and a multiply by a
constant) halved that overhead. A rotated entity still computes both.
Checking it
Cycle counts do not show correctness, and a projection rewrite can be off by
one pixel without looking wrong. The check is the flicker article's OAM sampling, made byte-exact: connect to the emulator's
GDB stub, let a few frames pass so startup settles, read the 1 KB of hardware
sprite memory, and compare it with the same read from the unmodified ROM.
IDENTICAL: 1024 bytes of OAM match exactly
This holds for both input_tester (unrotated text) and wordle
(rotated): all 128 sprite entries have the same position, tile, palette bank
and affine flags in both ROMs.
The numbers
Steady-state averages, cycle_probe.py against framer_gba_wait_vblank:
| Example |
Before |
After |
Change |
|---|
| input_tester (unrotated text) |
~684800 cycles/frame |
~660650 cycles/frame |
~3.5% faster |
| wordle (rotated word cloud) |
~810400 cycles/frame |
~814470 cycles/frame |
~0.5% slower |
input_tester is the representative case: a HUD-style scene with static,
unrotated labels. wordle's word cloud is a rotation showcase and the one
case where the change gives a little back. Closing that gap would need two code
paths, fixed-point when nothing is rotated and float when something is. I did
not add them: more branching in a dense function, for a demo scene rather than
the 18 FPS HUD case.
What is left
~3.5% is not the fix for an 18 FPS scene. The per-entity layout call and
framer_color_bank_acquire() were never bracketed like the projection math,
and either may hold more cost. Next step: the same two-breakpoint measurement
on them.
Introduction
The article about bullet pools ended with a
number: on the Game Boy Advance, a pool of bullets stops being fully
visible at 121 of them, and on the Nintendo DS at 126. Both consoles have
128 hardware sprite entries (OAM), and a few of them always go to the
player, the target and the text. Past that number, the renderer runs out
of entries and has to stop drawing.
Which bullets stop being drawn? The engine's first answer was the last ones
in the array, which is wrong for a reason unrelated to performance. The second
answer is cheaper and older, and an emulator can check that it works.
Note
framer-engine is a personal side project. The source code will be
made publicly available once the engine reaches a sufficient level of
maturity.
The first answer: the same ones, every frame
A sprite batch is drawn in array order, and the loop stops as soon as there
is no OAM entry left. With 200 bullets and room for 121, the same 79
bullets, the ones at the end of the pool, are skipped in every frame. They
are never drawn, and a bullet that is not drawn still moves and still hits
the player. The player dies to something that was never on the screen.
The engine already had one tool for this, and it is the right one for
most of the problem: a priority per batch. A batch with a lower priority
number is drawn first and so gets its OAM entries first; the batches that
matter least lose theirs. On the GBA, two stationary pools of 100 bullets
that together overflow OAM behave as expected: the one created second but
given priority 0 kept all 100 of its sprites, and the one created first,
with priority 200, kept 22.
/* The enemy's bullets decide whether the player lives. */
framer_sprite_batch_set_priority(world, enemy_pool, 0);
/* The player's own shots and the sparks come after. */
framer_sprite_batch_set_priority(world, shot_pool, 200);
Priority decides between batches. It says nothing about what happens
inside the one that does not fit, and the pool that loses is still cut
off at the same element every frame.
The second answer: start where you stopped
The consoles' own games had this problem first. A Famicom can draw eight
sprites on a scanline and sixty-four in all, and the shoot-'em-ups of that
era did not pretend otherwise: when a boss made of many segments crossed a
line, some of its sprites were missing. Players know the fix as flicker:
the missing sprites change from one frame to the next. Every sprite is on
screen on some frames, and at 60 frames a second the eye reads a dim sprite
rather than a hole. Recca is a
well-known example. The hardware did not do this; the games did, by rotating
the order they wrote their sprites in.
The same rotation fits a batch in a few lines. Each frame, a batch that
has opted in starts drawing at the element where the previous frame
stopped, and wraps around to the front when it reaches the end:
int n = framer_sprite_batch_count(batch);
int start = framer_sprite_batch_start(batch);

for (k = 0; k < n; k++) {
    i = start + k < n ? start + k : start + k - n;
    q = framer_sprite_batch_get(batch, i);

    if (s_next_oam_slot >= GBA_OAM_HW_SLOT_COUNT) {
        framer_sprite_batch_resume_at(batch, i);
        return;
    }
    /* ... write the OAM entry for q ... */
}
framer_sprite_batch_resume_at(batch, 0);
When the whole batch fits, the loop finishes, the resume point goes back to
zero and nothing rotates. When it does not fit, the element that was
refused is the one the next frame starts with. The first frame draws
elements 0 to 120 of 200, the second draws 121 to 199 and then 0 to 41, the
third starts at 42, and so on. Every element is drawn about 60% of the
frames, and which ones are missing keeps moving.
Where the index lives
The resume index has to survive from one frame to the next, and the
obvious place, a field of the batch's own component, does not work: a render
system is handed a copy of the component, so a write to it is lost. A
second component would work, but the static ECS this engine runs on GBA and
NDS has a fixed table of components, and on the GBA that table is nearly
full (the
article about it explains the budget). So the
index sits in a small table in sprite_batch.c, keyed by the address of
the batch's elements and sized for the sixteen batches a frame can draw. A
batch that does not find a slot is simply not remembered, and draws from
the front each frame, which is what a batch without flicker does anyway.
The only change to the component itself is one byte, the flag.
It is off by default, with one call to turn it on:
framer_sprite_batch_set_flicker(world, shot_pool, 1);
The desktop backends ignore it, since they have no OAM and draw everything.
Not for the enemy's bullets
Flicker is the right trade for effects, sparks and the player's own shots,
where a missing sprite on one frame costs nothing. It is the wrong one for
the bullets that can kill the player. A bullet that blinks is harder to
read than one that is steadily absent from a crowd, and at 60% visibility
it still hits on the frames it is invisible. Those bullets belong in a
batch that always fits, at the lowest priority number. That advice is
written next to the API in the engine's docs, because the mechanism makes it
easy to get wrong.
Checking it
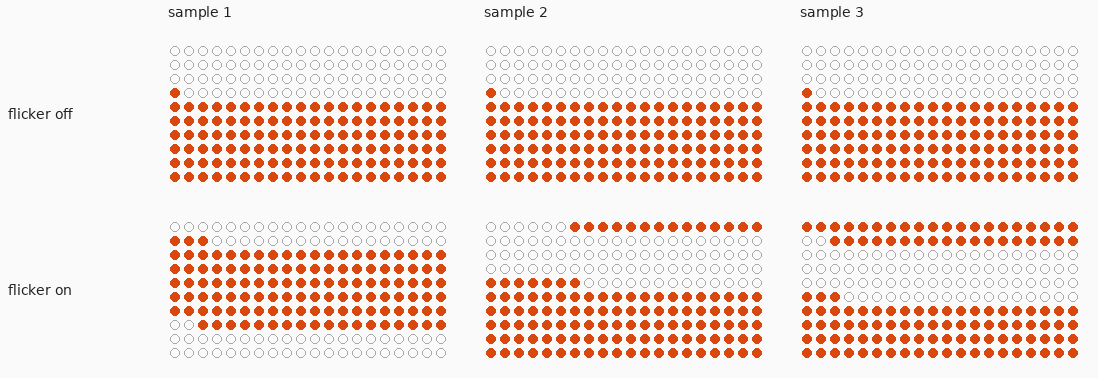
The claim to test is narrow: with flicker on, every bullet is drawn on some
frame, and with it off, the same bullets never are. A screenshot cannot show that, since one frame looks like any
other, so the check reads the OAM.
The test program is the bullets example with a pool of 200 stationary
bullets laid out in a grid of 20 by 10, which never move. A script connects to
the emulator's GDB stub, lets the program run for a random fraction of a second, stops it, reads the 1 KB of OAM,
and picks out the bullets, which are the 8 by 8 sprites that share the most
common tile. It does that dozens of times and counts how many different
positions it ever saw.
On the GBA, in mGBA, with room for 121:
| Flicker |
Samples |
Bullets drawn per sample |
Distinct positions ever drawn |
|---|
| off |
60 |
121 to 128 |
122 |
| on |
60 |
121 |
200 |
The "off" row is noisier than it should be: the per-sample count reached 128
and 122 positions were seen, where 121 is the most that fits. I did not track
down the difference. It is small next to 122 against 200, but the sampler is
not exact on the GBA.
On the DS, in melonDS 1.1, with room for 126, the program toggles the flag
itself every 180 frames, so one launch gives both rows, and the script
reads the current flag from a global at each stop:
| Flicker |
Samples |
Bullets drawn per sample |
Distinct positions ever drawn |
|---|
| off |
82 |
126 |
126 |
| on |
78 |
126 |
200 |
In both cases the number drawn at any moment is unchanged: flicker changes
which sprites are drawn, not how many. The figure shows three GBA samples per
setting, taken a second or so apart, with OAM positions mapped back onto the
20 by 10 grid:
All of this ran on emulators (mGBA, melonDS), none on hardware, and the
per-scanline limits were not checked.
What is left
The rotation only deals with the whole-OAM limit, the 128 entries. Both
consoles also limit how many sprites can be on one scanline, and that
limit can be hit by a wide row of bullets before the 128 total, so it is next.
Also planned: a way to report how many sprites a frame used, so a game can see
its budget without a debugger, and a priority for single sprite entities and
text, which today are always drawn before every batch.
Introduction
The GBA cycle-level optimization article and the
one on faking point lights on the DS GPU share a
premise: these CPUs have no floating-point unit, and every vertex costs
something somewhere. The GBA pays in rasterizer cycles. The DS has a hardware
3D engine, so it pays elsewhere, in a part of the frame I had not looked at.
Note
framer-engine is a personal side project. The source code will be
made publicly available once the engine reaches a sufficient level of
maturity.
The framer-engine spinning_shapes example puts a cube, a sphere and
a cone on screen, each rotating, and a button toggles between drawing them
solid and drawing them as wireframes. On the DS it ran at 60 FPS in solid
and about 20 in wireframe. Wireframe should be cheaper: fewer pixels filled,
no lighting. The bug report was that a debug view ran three times slower than
the real thing. A second question followed: how do you measure a frame on a
platform you can only run in an emulator?
How wireframe gets drawn on a GPU that has no lines
The DS 3D engine draws triangles and quads, and nothing else:
libnds' glBegin() takes only triangles and quads (and their strips), with
no line primitive. The hardware has a wireframe polygon mode, selected by a
polygon alpha of zero, but it outlines a polygon's own edges. The engine's
meshes keep a separate list of the edges to draw, and for a sphere that list
leaves out the diagonals that split each patch into two triangles; the
hardware mode would draw them. (I reasoned this out and never tried the mode.)
So wireframe here is a thin, flat, unlit quad along every edge.
The quad has to be widened perpendicular to the edge, in a direction that
makes sense for a convex mesh centered on its origin. The code takes the
direction from the origin to the middle of the edge and removes the part along
the edge:
/* per edge, every frame */
float edge_len = sqrtf(edge[0]*edge[0] + edge[1]*edge[1] + edge[2]*edge[2]);
float mid_len  = sqrtf(mid[0]*mid[0] + mid[1]*mid[1] + mid[2]*mid[2]);
dir[k]    = edge[k] / edge_len;          /* k = 0..2 */
radial[k] = mid[k]  / mid_len;
dot       = radial[0]*dir[0] + radial[1]*dir[1] + radial[2]*dir[2];
width[k]  = radial[k] - dot * dir[k];    /* perpendicular to the edge */
width_len = sqrtf(width[0]*width[0] + width[1]*width[1] + width[2]*width[2]);
width[k]  = width[k] / width_len * half_width;
/* then four vertices: a -/+ width, b +/- width, as 4.12 fixed point */
On a PC this is unremarkable. On the DS's ARM9 it is three square roots, nine
divides, roughly fifty multiplies and adds and twelve float-to-fixed
conversions per edge, every frame, each a call into a software
floating-point routine.
Why not just look at the frame rate
Reading the emulator's frame counter tells you least. melonDS' speed varied a
lot between runs in earlier sessions, so wall-clock time and its frame counter
say more about the host than the console. The emulated hardware timers hold
still: the same ROM executes the same instructions and the timers count them
the same way every run.
libnds exposes two of them chained into a 32-bit counter through
cpuStartTiming() and cpuEndTiming(), which return ticks of the
hardware timer clock (about 33.5 MHz, the bus clock; the ARM9 itself runs
at twice that). A throwaway build wraps the 3D render system and stores the
result in a global per render mode:
volatile uint32_t g_diag_ticks[2];   /* [0] solid, [1] wireframe */
volatile uint32_t g_diag_count[2];

static void nds_hw3d_render_system(framer_iter_t *it)
{
    int w = framer_render_mode_get_override() ==
            FRAMER_RENDER_MODE_FORCE_WIREFRAME;

    cpuStartTiming(0);
    nds_hw3d_render_system_impl(it);   /* the real system, unchanged */
    g_diag_ticks[w] = cpuEndTiming();
    g_diag_count[w]++;
}
A copy of the example toggles the render mode itself every 120 frames, so
one emulator launch produces both numbers, and the globals are read over
melonDS' GDB stub, with their addresses taken from nm on the ARM9 ELF:
ticks = struct.unpack('<2I', bytes(rsp.read_mem(sock, tick_addr, 8)))
count = struct.unpack('<2I', bytes(rsp.read_mem(sock, count_addr, 8)))
Two runs agreed to within a few ticks, which makes the figures usable:
| Mode |
Ticks per frame |
Time |
|---|
| Solid |
317,950 |
9.5 ms |
| Wireframe |
1,414,850 |
42 ms |
A 60 FPS frame is 16.7 ms. Solid fits with room to spare. Wireframe takes
42 ms in the 3D pass alone, more than two vertical blanks, so the frame lands
on the third and the screen updates every 50 ms: 20 FPS.
Where 1.4 million ticks go
The meshes are not small. The sphere has 20 sectors and 10 stacks, which is
430 edges and 360 triangles; the cone adds 40 edges and 40 triangles and
the cube 12 and 12. A wireframe frame therefore builds 482 quads, and a
solid frame submits 412 triangles. Dividing:
- wireframe: 1,414,850 / 482, about 2,900 ticks per edge, roughly 5,900
ARM9 cycles for the arithmetic above;
- solid: 317,950 / 412, about 770 ticks per triangle, which is a normal and
three vertices converted to fixed point and handed to the GPU, with no
square root and no divide anywhere in it.
The GPU did not set the cost in either mode. The CPU did, and in wireframe it
spent 42 ms of every frame, two and a half frame budgets, on arithmetic whose
answer is the same every frame.
The data never changes
The cube is the same cube every frame. Only the model matrix changes, and the
GPU applies that itself from a matrix stack. Every square root and divide in
that loop recomputes the same four vertices as 1/60th of a second earlier.
The DS has a mechanism for exactly this: a display list, a block of
pre-packed geometry-engine commands that glCallList() sends to the GPU
FIFO by DMA. Its layout is the hardware's own FIFO layout, documented in
GBATEK: a first word with the number of words that follow,
then groups made of one word holding up to four command ids, one per byte,
followed by the parameter words of those commands in order. A quad with
four vertices comes out as:
word 0   count
word 1   BEGIN_VTXS | VTX_16 | VTX_16 | VTX_16     (0x23232340)
word 2   1                                          (GL_QUADS)
word 3   x0 | y0 << 16                              vertex 0
word 4   z0
word 5   x1 | y1 << 16                              vertex 1
word 6   z1
word 7   x2 | y2 << 16                              vertex 2
word 8   z2
word 9   VTX_16 | NOP | NOP | NOP                   (0x00000023)
word 10  x3 | y3 << 16                              vertex 3
word 11  z3
The packer is about eighty lines of plain C with the command ids defined next
to it (BEGIN_VTXS is 0x40, NORMAL 0x21, VTX_16 0x23). It has no
libnds dependency, so it is unit-tested on the desktop, with the layout above
as one test. libnds documents one trap: END_VTXS does nothing and is
reported to cause trouble in a DMA'd list, so lists never contain it.
void gx_dl_cmd(struct gx_dl *dl, uint8_t id, const uint32_t *params, int n)
{
    if (dl->slot == 4) {                 /* open a new command word */
        dl->cmd_at = dl->len++;
        dl->words[dl->cmd_at] = 0;
        dl->slot = 0;
    }
    dl->words[dl->cmd_at] |= (uint32_t)id << (8 * dl->slot);
    dl->slot++;
    for (int i = 0; i < n; i++)
        dl->words[dl->len++] = params[i];
}
The renderer bakes a mesh the first time it is drawn in a given mode: the
edge quads for wireframe, the triangles with their flat normals for solid.
After that a draw is a colour, a glCallList() and nothing else. Only
what is identical on every draw goes into a list; the colour, the
material, the polygon format and the model matrix stay with the caller, so
the same list serves every object that shares a mesh. Two kinds of object
keep the old triangle-by-triangle path because they vary something a list
would have to hold: objects with a colour per face, since the material
changes between faces, and textured ones, since their texture coordinates
are scaled by the texture's size. The old immediate wireframe code also
stays, as the fallback for a mesh that cannot be baked: more than eight
different meshes in a program, or no memory left for the list.
Results
Same scene, same instrumented build, measured the same way:
| Mode |
Before |
After |
Change |
|---|
| Solid |
317,950 |
18,500 |
17 times cheaper |
| Wireframe |
1,414,850 |
24,450 |
58 times cheaper |
The wireframe pass goes from 42 ms to 0.73 ms and solid from 9.5 ms to
0.55 ms. The two modes now cost about the same, which is what the original
bug report had assumed all along.
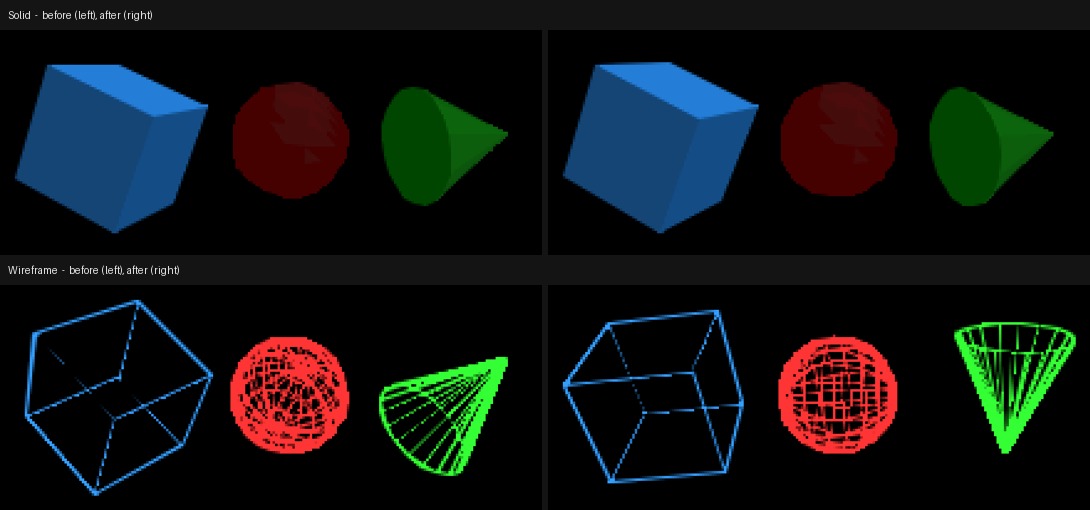
The picture must stay the same. The figure shows the top screen before and
after, captured in the same runs as the numbers. The shapes are at different
points of their rotation because the demo keeps spinning; shading and lines
are the same.
Three caveats:
- The GPU still has to consume the list. glCallList() flushes the
list from the data cache, starts the DMA and waits for it to finish, and
the DMA only completes once the geometry FIFO has accepted the data. melonDS
models the geometry engine's timing only roughly, so on a real console
that wait will be longer than 0.7 ms. It is waiting on the GPU, not
computing, and nothing was measured on real hardware.
- The first draw pays the old price once. Baking runs the original math
one time per mesh and mode, so the first frame in wireframe still does
what every frame used to. It is a one-off hitch rather than a rate, and
an unmeasured one.
- Lists cost memory. About 15 KB for the sphere's wireframe and 12 KB
for its solid list, allocated from the heap and held for the life of the
program.
What is still on the slow path
Objects with per-face colours and textured objects still submit triangle by
triangle, so a scene dominated by them gets none of this. Both can be baked: a
per-texture-size list for the textured case, one list per colour run for the
face-coloured one. They are next, measured the same way.
Introduction
The previous article described the static, no-heap
Entity Component System framer-engine runs on GBA and NDS: fixed tables of
component slots and entities, sized for a machine with no malloc(). With
today's component set the table has room for 64 real entities. A caravan-style
vertical shoot-'em-up, the engine's first playable milestone, wants several
hundred bullets on screen in a dense pattern. The entity table cannot grow to
fit that, and the pattern cannot cap itself at 64 shots.
Note
framer-engine is a personal side project. The source code will be
made publicly available once the engine reaches a sufficient level of
maturity.
The usual answer is not to make every bullet an entity. The simulation, a flat
array of structs advanced by one system, was easy. Drawing that array without
opening a second path in the renderer took two attempts. The first shipped,
worked, and was wrong in a way no test would catch. The second was smaller,
matched a pattern the engine already had, and surfaced three bugs across three
rendering backends, none about bullets.
The first answer: a queue that isn't an entity
Hundreds of short-lived things, updated and drawn every frame and never
addressed individually, suggest a per-frame queue: a flat array of draw
commands (position, sprite, frame), reset each frame, appended to by whatever
wants something drawn and consumed once by the renderer. A bullet pool fits
exactly, pushing one entry per live bullet after the physics step, and needs
nothing from the ECS: no entity, component or query.
That was the problem. Everything else the engine draws (a sprite, a tilemap, a
HUD label) is an entity with a component, and every renderer's draw phase is
systems iterating queries. A queue fed by application code and drained by the
renderer is a second path. The entity-inspection API cannot see it, capability
queries do not know it exists, and the debugging tools built on "the ECS is the
whole scene" miss it. Bullets appeared in the right place at the right speed,
but elements without an entity bypass the engine's core model. It is a
different design that happens to render the same pixels.
The second answer: an entity that stands for many
framer-engine already had a component for this class of problem: a
Tilemap is one entity whose component points at a grid the owner keeps,
and the renderer draws the whole grid from that entity. Nothing in "many drawn
things, one external memory, one component pointing at it" is specific to
tiles. The rewrite generalizes it as SpriteBatch, and the bullet pool
becomes one more caller instead of a bespoke path:
struct framer_batch_sprite {
    int32_t x, y;       /* center, world units, fixed point */
    uint32_t texture;
    uint8_t frame;
    uint16_t size;       /* drawn size, world units, fixed point */
};

struct sprite_batch {
    const void *first;   /* owner's element array */
    const uint16_t *count; /* owner's live-element count */
    uint16_t stride;      /* bytes between elements */
};
A framer_bullet has its own struct framer_batch_sprite as its first
field, so the pool's storage array is the SpriteBatch element array, with
no copy and no second buffer to keep in sync.
framer_bullet_pool_entity_create() gives the pool's one entity a
BulletPool component, stepped each frame by a physics system, and a
SpriteBatch component built from the same array, drawn each frame by the
renderer. Every draw phase still iterates a query and draws what it finds.
The bullets stay out of the 64-slot entity table, and everything drawn is
reachable from an entity.
Every renderer backend has to learn to draw the new component independently,
which gave each one a chance to get it wrong.
Bug 1 (Vulkan): a guard that was checking the wrong component
Each backend's sprite system is imported once per world, so it needs a guard
against importing twice. Comparing the stored world pointer with the current
one breaks when a different world is allocated at the same address, which
every test here does by tearing a world down and creating a fresh one. The
convention in the renderer imports is to also check that a component the
import function itself registers is present on the world.
The check written for SpriteBatch tested the wrong component:
/* Wrong: Sprite is registered by the renderer's own import, before
 * this function ever runs -- it says nothing about whether THIS
 * function has run on this particular world. */
if (s_world == world && FRAMER_COMPONENT_IS_REGISTERED(world, Sprite))
    return;
On a fresh world reusing a previous world's address, Sprite is already
registered by the caller, earlier in the same
framer_sprite_system_import(), before the guard runs. The check reports
"already set up" on the first call and the function returns without
registering SpriteBatch or its draw system. Sprites drew; batches never
did.
A test caught it. The new pixel-readback test for SpriteBatch (draw an
element, read the pixel back, expect it filled) passed on the software and
OpenGL backends and failed on Vulkan, whose suite happened to run a batch test
on a world at an address a prior test had used. The fix checks the component
this function registers:
if (s_world == world && FRAMER_COMPONENT_IS_REGISTERED(world, SpriteBatch))
    return;
The OpenGL and software backends had the identical guard, found by
inspection before either failed a test. Both got the same fix and were
verified.
Bug 2 (OpenGL): reading back a write that hasn't happened yet
The OpenGL backend compiles its default shaders lazily, on first request, and
caches them in the world's Shader singleton component:
const struct shader *shaders = FRAMER_GET(world, FRAMER_ID(Shader), Shader);
if (!shaders) {
    unsigned int sprite = framer_shader_create(...);
    /* ... compile the other three default shaders ... */

    FRAMER_SET(world, FRAMER_ID(Shader), Shader, .sprite_shader = sprite, /* ... */);
    shaders = FRAMER_GET(world, FRAMER_ID(Shader), Shader);
    if (!shaders)
        return 0;
}

switch (type) {
case SHADER_TYPE_SPRITE: return shaders->sprite_shader;
/* ... */
}
This assumes a component write takes effect immediately. It does not: a write
issued inside a running system is staged and merged once every system in that
step has finished. A second system in the same step can see it, but the call
that made the write cannot read it back. That is an ordinary property of this
ECS. Every other caller of framer_shader_get_default() came after something
upstream (loading a level, spawning a player) had already asked for a shader on
an earlier frame, so the singleton existed.
The SpriteBatch draw system is the first thing in a new scene with nothing
upstream: no mesh, no plain sprite, just a bullet pool's entity. On the first
frame its render system is the first caller of framer_shader_get_default().
The write lands, the read-back in the same call finds nothing, the function
returns 0, and that frame renders every batch element with no shader bound.
The ECS timing is fine; the fix stops reading back what was just staged:
struct shader created = {.sprite_shader = sprite, /* ... */};

framer_component_set(world, FRAMER_ID(Shader), FRAMER_ID(Shader), &created);
return shader_of_type(&created, type);
Bug 3 (all three desktop backends): drawn correctly, in the wrong order
The first two bugs were "nothing drew". In the third, every bullet drew at the
right position, size and texture, but the entity that fired them disappeared
behind its own bullets once enough piled up at its position.
SpriteBatch and the per-entity Sprite draw are separate systems in the
same ECS phase, and nothing said which goes first. On GBA and NDS the hardware
settles it: OAM sprites carry a priority, and entity sprites are drawn at a
higher priority than batch elements, so an entity is in front of a batch
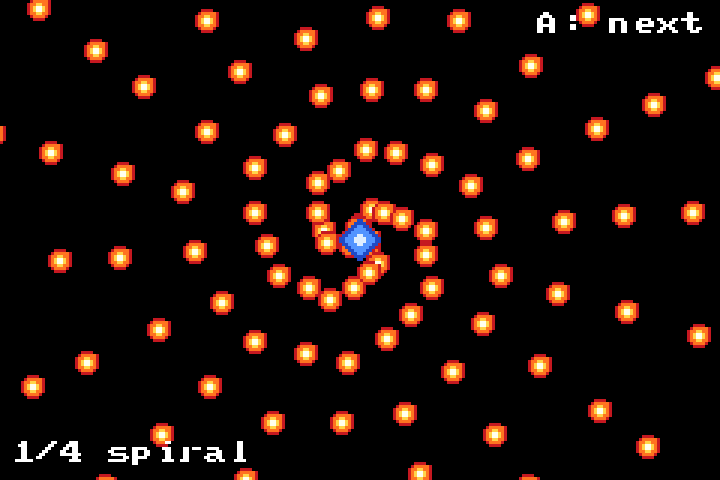
whatever the system order. Sampling the OAM through mGBA's debug stub mid-run
confirms it: the emitter (the round blue sprite at the center) sits in front of
the spiral it fired:
The three desktop backends (OpenGL, Vulkan, software) have no such guarantee:
draw order is their only ordering mechanism, and the two systems registered in
whatever order the import code called them, which put SpriteBatch after the
entity sprite system. Sampling framebuffer pixels at the emitter's position
every fifty frames of a Vulkan run shows the failure: the emitter's blue for
hundreds of frames, then, once enough live bullets reach that pixel, whatever
bullet is passing through it:
frame  350: 2850c8 5a96ff 5a96ff 5a96ff 2850c8   (emitter blue)
frame  750: 2850c8 5a96ff 5a96ff 5a96ff 2850c8   (emitter blue)
frame  800: c81e28 ff7828 ffdc50 ff7828 c81e28   (bullet red/orange)
frame 1200: c81e28 ffdc50 fffff0 ff7828 c81e28   (bullet, still)
The fix declares the order explicitly instead of relying on registration
order, on every desktop backend:
static const struct framer_system_dep batch_deps[] = {
    {.before = "sprite_render_system", .after = NULL}};

framer_system_register(world, "sprite_batch_render_system",
                        FRAMER_PHASE_ON_UPDATE,
                        sprite_batch_render_system, bq, batch_deps, 1);
A new renderer test pins it down: a red entity sprite and a white batch
element on the same pixels, asserting the pixel reads back red.
Verification: one bug per backend, so one check per backend
The design is not backend-specific, but each backend had its own bug, so each
was checked separately. The desktop pixel-readback tests (software, OpenGL,
Vulkan) ran the same three scenes. examples/bullets was cross-compiled for
GBA and NDS and its OAM sampled through mGBA's debug stub, the technique the
dithering article used to catch a hardware-only bug. Every
GBA example ROM was booted headlessly to check that a related fix did not
regress startup: one more component pushed the fixed-stride storage layout past
EWRAM, so component storage is now pooled.
One result was the same everywhere I checked: with the spiral pattern running
continuously, the live bullet count settles in the high 90s on GBA, OpenGL and
Vulkan alike.
Where this goes next
FRAMER_STATIC_MAX_COMPONENTS (40) and FRAMER_STATIC_MAX_ENTITIES (104,
leaving 64 for game use) both grew slightly to fit the new component without
pushing the pooled storage past EWRAM on GBA. What remains for the bullet pool
is measuring and documenting the per-target bullet ceiling. The capacity
constants (examples/bullets uses 128 on GBA/NDS, 1024 on desktop) were
picked before there were numbers to size them against.
Introduction
The previous article was about squeezing cycles
out of framer-engine's GBA renderer. This one covers what has to be settled
before that work is possible: how to run an Entity Component System, the
pattern the engine is built around, on a console with 32KB of fast RAM, 256KB
of slow RAM, no operating system and no usable malloc().
framer-engine answers with a second, much smaller ECS implementation behind
the same interface as the desktop one. Component definitions, systems and
queries are identical between a PC build and a GBA build. Only one file
differs: which world.c is linked.
Note
framer-engine is a personal side project. The source code will be
made publicly available once the engine reaches a sufficient level of
maturity.
Two ECS backends, one interface
The default backend is Flecs, a full-featured ECS used for desktop and
handheld targets with a real OS (PSP, 3DS, Switch, PC). It provides archetypes,
queries, observers and relationships, and all of that bookkeeping assumes a
heap that grows and shrinks as entities and component types come and go. The
GBA has 32KB of IWRAM and 256KB of EWRAM, both fixed-size and fully accounted
for from boot, with no MMU and no OS to page anything in. There is no heap.
A second full-featured ECS sized to that budget would be a lot to maintain for
a problem that does not need it. GBA-class scenes hold a handful of objects
(examples/simple_cube uses one mesh and a camera, examples/spinning_shapes
three), not thousands, and the component types are fixed at compile time.
src/ecs/static/world.c, about 550 lines of plain C, is sized to that
instead of to Flecs:
/* Entities */
static bool s_alive[FRAMER_STATIC_MAX_ENTITIES];
static uint64_t s_comp_mask[FRAMER_STATIC_MAX_ENTITIES];

/* Component data store: row = component slot, column = entity slot.
 * Each entity slot is FRAMER_STATIC_MAX_COMPONENT_SIZE bytes wide. */
static uint8_t s_store[FRAMER_STATIC_MAX_COMPONENTS]
                       [FRAMER_STATIC_MAX_ENTITIES *
                        FRAMER_STATIC_MAX_COMPONENT_SIZE];
Every array is a fixed-size global sized by compile-time constants. Nothing in
this file can fail by running out of memory unpredictably. It can only run out
of array slots, a number known before the program starts.
Both backends sit behind the same include/framer/ecs.h: framer_world_t,
framer_component_register(), framer_query_create(),
framer_system_register() and the FRAMER_GET/FRAMER_SET/
FRAMER_FIELD macros. A component defined with
FRAMER_COMPONENT_DEFINE(Velocity) and a system registered with
framer_system_register() compile and run unchanged on either. A single Meson
option selects the backend, -Decs=flecs or -Decs=static. GBA's cross
file pins it to static because Flecs needs an OS, and the build refuses to
configure otherwise.
Entities are array slots
An entity here is a 1-based index into those parallel arrays.
framer_entity_create() claims the lowest dead slot, first-fit:
framer_entity_t framer_entity_create(framer_world_t *world)
{
    int i;

    for (i = 0; i < FRAMER_STATIC_MAX_ENTITIES; i++) {
        if (!s_alive[i]) {
            s_alive[i] = true;
            s_comp_mask[i] = 0;
            if (i + 1 > s_entity_high)
                s_entity_high = i + 1;
            return EID(i);
        }
    }
    return 0; /* pool exhausted */
}
That is the whole allocator. There is no free list and no fragmentation, since
every slot has the same size and a compile-time address. The price is
deliberate: destroying entity 5 and creating a new one immediately returns ID
5 for a different logical entity, and there is no generation counter to tell
them apart. For a handful of objects that mostly live for a whole level, that
is acceptable. test_entity_slot_recycled_first_fit pins it down so it
stays a known property.
Components: a bitmask and a flat array
Each entity slot carries one uint64_t bitmask with one bit per registered
component type. framer_component_set() is a memcpy into a fixed-stride
row of s_store plus a bit set:
void framer_component_set(framer_world_t *world, framer_entity_t e,
                          framer_id_t id, const void *data)
{
    int ei = EIDX(e);
    int ci = cidx(id);
    /* ...bounds and liveness checks elided... */
    memcpy(&s_store[ci][ei * FRAMER_STATIC_MAX_COMPONENT_SIZE], data,
           s_comp[ci].size);
    s_comp_mask[ei] |= ((uint64_t)1u << ci);
    s_any_mask |= ((uint64_t)1u << ci);
}
A query is a precomputed mask built from the component ids it asks for, and
matching an entity is one AND and one comparison
((s_comp_mask[ei] & mask) == mask). The uint64_t is also the ceiling on
distinct component types in a world: 64. That is plenty for a retro scene,
and it stops anyone building something Flecs-shaped on top.
A silent NULL deref vs. a loud abort()
The most important property of this backend is what happens when a limit is
hit. framer_component_register() originally returned 0 when a component
was too big or the registry was full, like the rest of the API. A 0 component
id then does damage downstream: framer_query_create() skips it when
building the mask, and the system that registered the query calls
FRAMER_FIELD() on a field that was dropped, dereferencing NULL on its next
matching entity. This happened on a real GBA build: a Text component of 288
bytes against a 64-byte cap, and 17 component types against a cap of 12. The
crash was a NULL-pointer SIGSEGV inside a render system, two layers away from
the mistake, not "your component is too big".
The fix removes the silent path:
if (size > FRAMER_STATIC_MAX_COMPONENT_SIZE) {
    fprintf(stderr,
        "framer_component_register: \"%s\" is %lu bytes, "
        "exceeding FRAMER_STATIC_MAX_COMPONENT_SIZE (%d)\n",
        name ? name : "?", (unsigned long)size,
        (int)FRAMER_STATIC_MAX_COMPONENT_SIZE);
    abort();
}
It uses abort() instead of assert() or a GCC/Clang builtin because this
backend also has to compile under cc65 and SDCC for 8-bit targets, and C89
abort() is the one failure primitive guaranteed everywhere. The tests check
the contract, not just the arithmetic: test_ecs_static_limits.c forks a
child, registers one component past the limit, and asserts the child died of
SIGABRT. That proves the fail-loud path fires.
On a backend made of fixed-size arrays, every hard limit is a wall. The choice
is hitting it with a clear message at the offending call, or with a corrupted
query and a crash three calls away. This backend fails loudly wherever a hard
cap exists.
Sizing the pools, and a second silent-failure bug
Each target's meson.build picks FRAMER_STATIC_MAX_COMPONENTS,
FRAMER_STATIC_MAX_ENTITIES and FRAMER_STATIC_MAX_COMPONENT_SIZE for
that platform. No universal default fits, because the engine registers its full
set of core components (Transform, Velocity, Sprite, Light,
Text, Camera and so on, 19 today) regardless of what an example uses:
# Embedded (system == 'none'):
-DFRAMER_STATIC_MAX_COMPONENTS=19
-DFRAMER_STATIC_MAX_ENTITIES=96
-DFRAMER_STATIC_MAX_COMPONENT_SIZE=64
MAX_ENTITIES=96 has its own bug behind it. Each registered component type,
not each entity created, reserves one sentinel slot from the same entity pool,
so the entities available to a scene are MAX_ENTITIES minus the number of
component types. At MAX_ENTITIES=64 and 19 components that left 45 usable
slots, enough for examples/simple_cube but one short of
examples/input_tester's 48 (47 on-screen panel entities plus a camera). The
failure was silent again: framer_entity_create() returned 0 once the pool
filled, and the caller wanting one more entity for a gamepad-axis label never
got it. The text did not appear and nothing in the logs said why. Raising the
cap to 96 (77 free after the 19 sentinels) fixed it. On GBA that costs about
544 bytes of IWRAM (three per-entity arrays scale with the cap), which I
checked against the build's free IWRAM margin before landing. On a 32KB budget
you measure.
As in the performance article, arm-none-eabi-size -A on a current GBA build
shows where this backend's memory goes. The flat component store
(19 × 96 × 64 bytes ≈ 114KB) goes in EWRAM's .sbss section: too big for
IWRAM, and zero-initialized by the startup code at no ROM cost:
#ifdef GBA
#define _FRAMER_STORE_ATTR __attribute__((section(".sbss")))
#else
#define _FRAMER_STORE_ATTR
#endif

static uint8_t _FRAMER_STORE_ATTR
    s_store[FRAMER_STATIC_MAX_COMPONENTS]
           [FRAMER_STATIC_MAX_ENTITIES * FRAMER_STATIC_MAX_COMPONENT_SIZE];
Everything else (alive flags, masks, the per-frame iterator's entity list) is
small enough for IWRAM, the GBA's fast 32KB memory, where the CPU wants its
hot data. On the current examples/simple_cube build that is roughly 19.5KB
of 32KB used. That leaves room for a component or two, and the number needs
rechecking whenever the component count grows, as the 96-entity change did.
The scan loop
framer_world_progress() walks every registered system in phase order and,
for each, scans entity slots up to the high-water mark (s_entity_high, one
past the highest slot any entity or component sentinel has occupied) looking
for bitmask matches. The sticky s_any_mask check skips the scan entirely
for systems whose component type no entity has ever had. That was the biggest
win in the previous article's performance work, covered there. The design point
here is that this is a linear scan over a flat array, not a sparse-set or
archetype lookup. That is right at GBA scene sizes (tens of entities) and wrong
at thousands, where you would reach for Flecs.
What this design gives up
Two backends exist so that these trade-offs are made once, explicitly, per
target:
- No entity generations. IDs are recycled immediately and look identical
to the entity that held them before.
- No archetypes, no sparse sets. Matching is a linear scan with a bitmask
test, not a cache-friendly iteration over exactly the matching entities.
Fine at dozens of entities, wrong past that.
- 64 component types in total, for the whole world. Not per query: every
component type in the engine, shared across every system. The current 19
leaves room, but adding a component means someone must recheck that ceiling.
- No relationships, hierarchies or observers. Flecs has all three. This
backend has entities, components and queries.
Flecs has these capabilities and this backend does not, and they are the
features that cost a heap, dynamic bookkeeping and memory use unknowable at
compile time, none of which a bare-metal ROM can afford.
Where this goes next
Every retro target on the roadmap has the same constraints: no OS, no heap, a
fixed memory map and a known component set. The 32-bit-era consoles mentioned
at the end of the previous article, starting with the PlayStation 1, have far
more RAM and a real GPU but still no OS and no desktop heap. I expect them to
use this static backend with much larger pool constants, not Flecs and not a
third ECS. Whether that holds on a real PS1 build is for a later article.